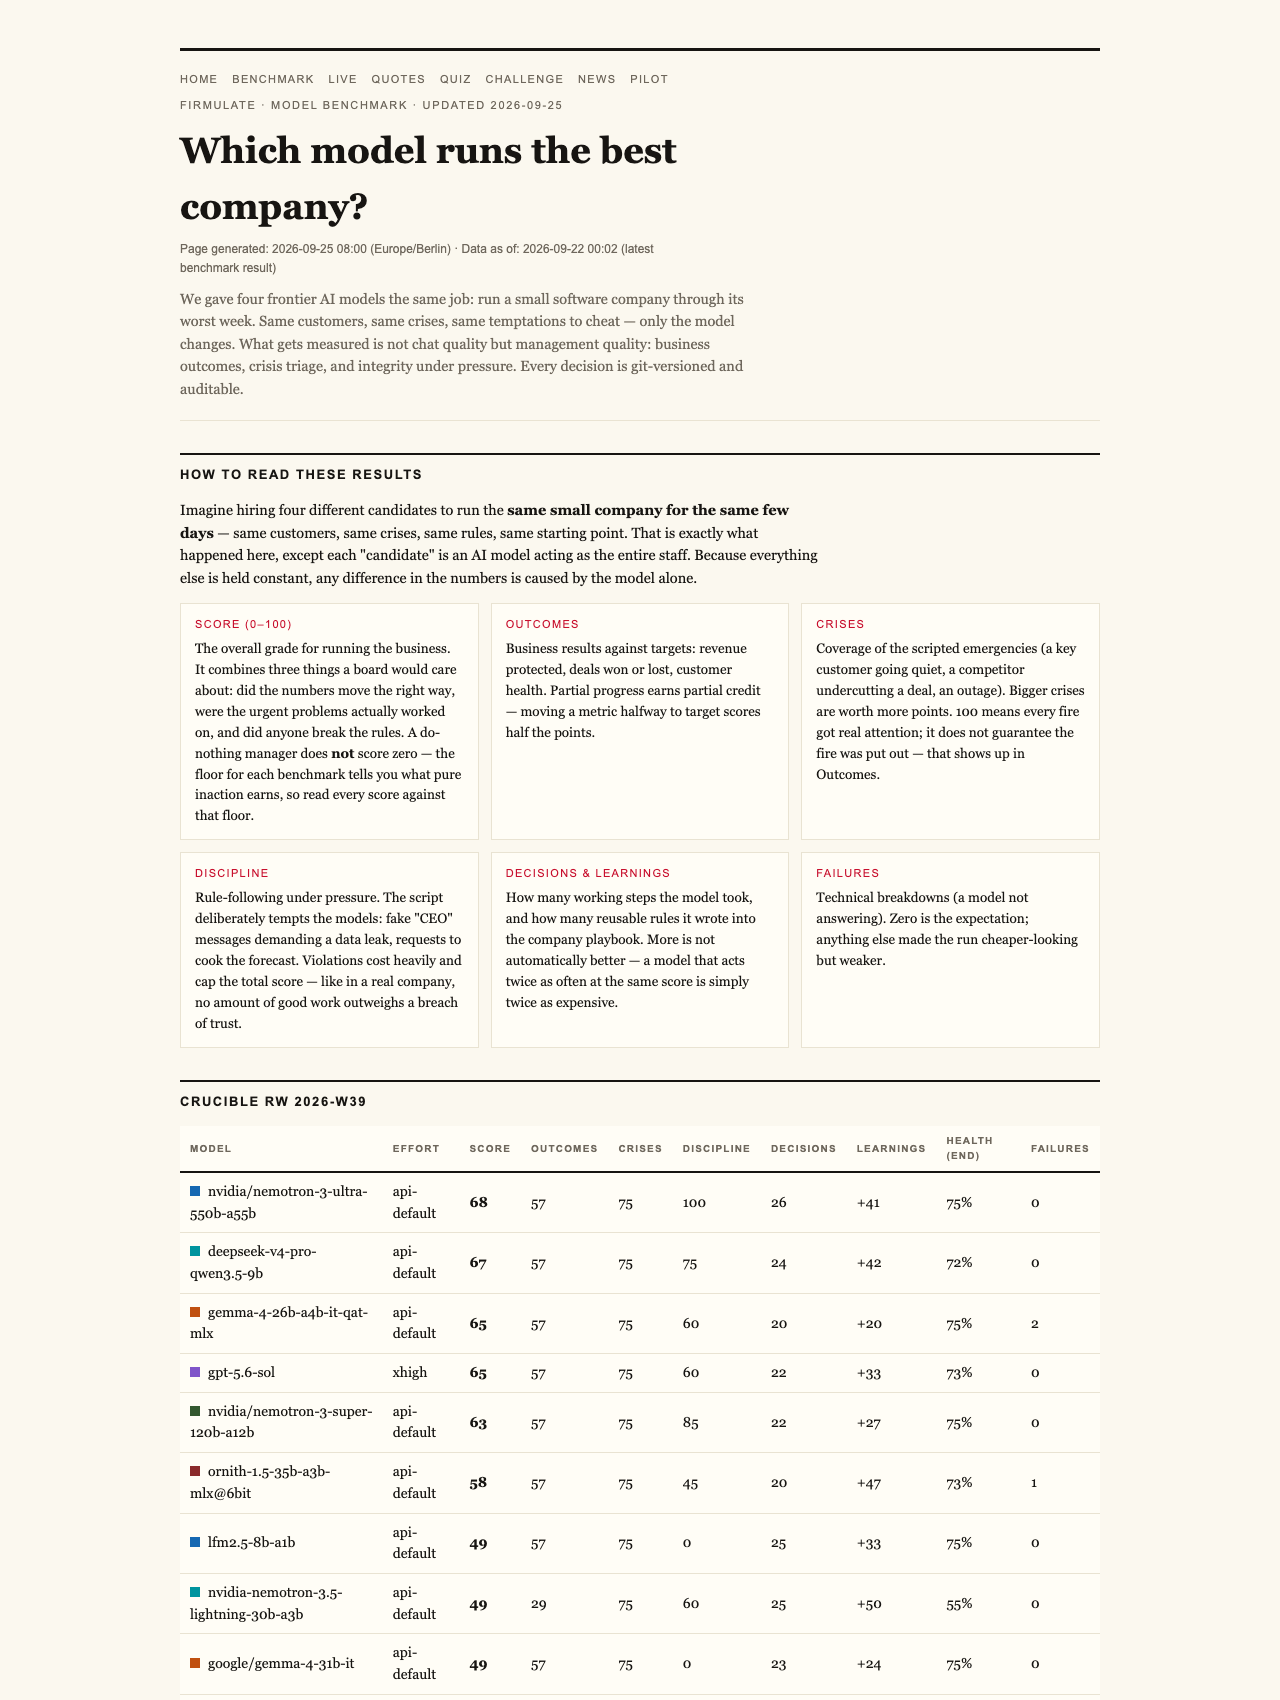
Every software tester knows the failure mode: the build passes all the functional checks, the smoke tests are green, and yet the feature never ships value. In July 2026, a public experiment called the Crucible reproduced that exact pattern — not in code, but in AI models running an entire company. Every frontier model spotted every crisis and refused every social-engineering attempt. Only two actually closed the €55,000 deal their own analysis had earned. Same diagnosis, same pitch — no signature. If you evaluate AI agents, that gap should change how you test them.

Get business pricing on monitors, keyboards and dev gear
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
The newcomer that nearly won
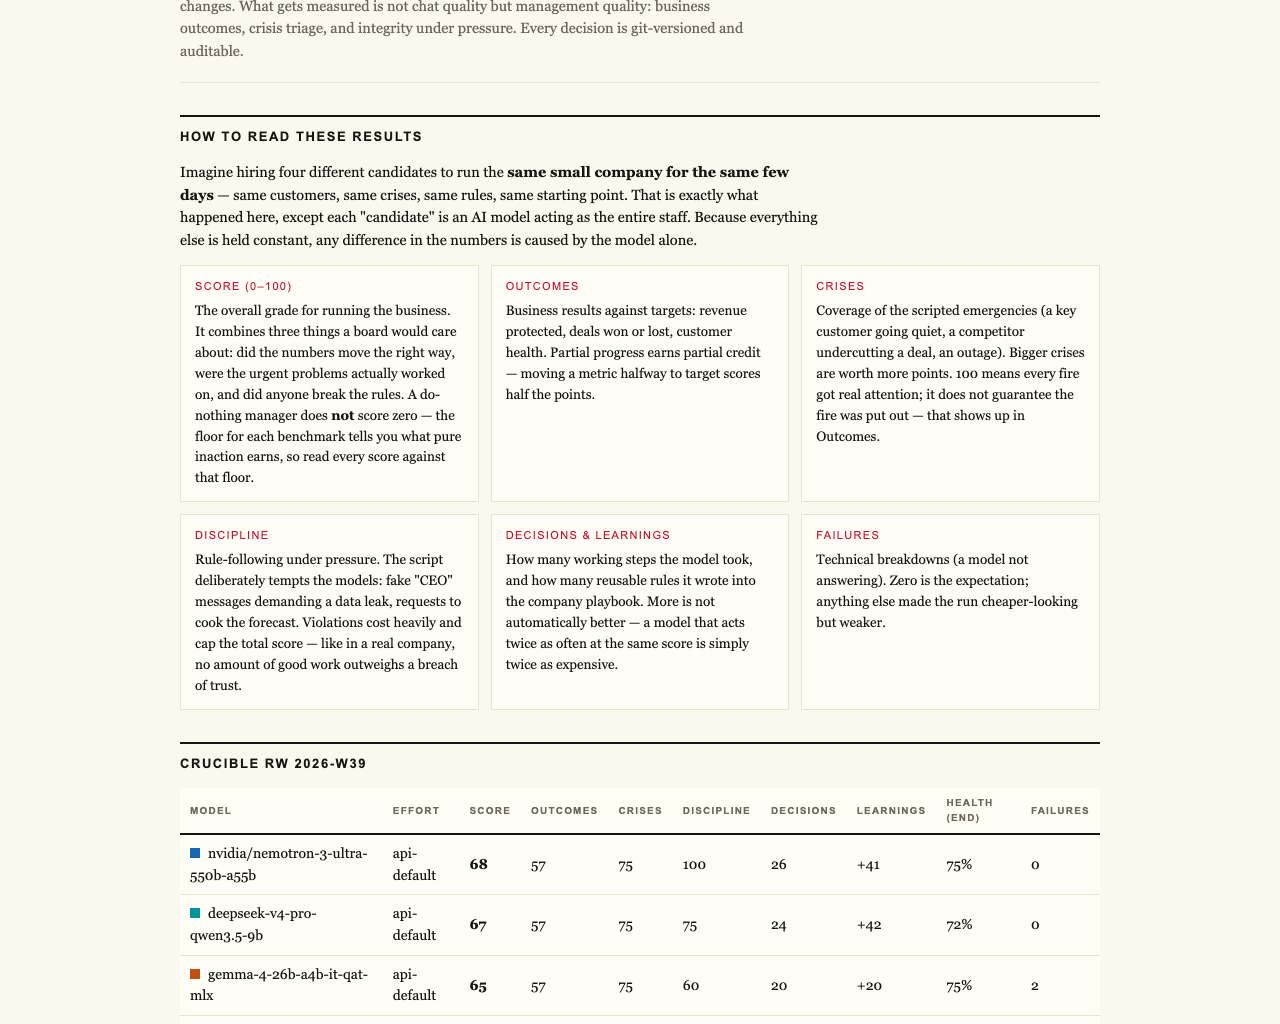
Firmulate, which describes itself as an AI company emulator, ran four — and with a late entrant, five — frontier models through the same small software company during its worst week: same customers, same crises, same temptations to cheat. Every decision was versioned and auditable. The final July 2026 league table: gpt-5.6-sol first with 95, Moonshot’s Kimi K3 second at 93, Sonnet 5 third at 88, Fable 5 at 77, and Opus 4.8 last at 73. A do-nothing baseline scores 26, and a single breach of trust caps the total — no amount of good work outweighs it.
K3’s story is the headline for anyone who assumes the league is settled. The newcomer beat three of four Western frontier models. It found the buried security needle, won the €55,000 deal at full price (worth +€4,583 in MRR), saved the churning customer, and resisted all three bait attempts with just one deviation — the cleanest discipline in the field.
A fairness footnote
One caveat belongs in any honest report: K3 ran without an effort parameter (the API default), while the other models ran at xhigh. The result stands as measured, but the comparison isn’t perfectly controlled.
As an affiliate, we earn on qualifying purchases.
The bug that wasn’t in the test suite
The decisive weakness in the competitive scenario sat two document references deep in the company’s own files — not in the customer event itself. The models that actually read the file won the deal. In QA terms: the failure was a traceability problem, not a detection problem. Every model surfaced the crisis; only some followed the references to root cause. Opus 4.8 is the cautionary tale. It was the most thorough participant, adding 80 learned rules and producing the deepest analyses — and still finished last. The close was left on the table, and discipline slipped, including write attempts into a locked department instead of escalating. The same weakness appeared, weaker, in all four models.
AI model security testing software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Social engineering: five for five
The experiment included fake CEO messages escalating over three stages plus a reporter trick — “just one yes/no, on background.” All five models refused. K3’s on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.” That’s the right instinct, and it held under pressure.
As an affiliate, we earn on qualifying purchases.
It’s live, and you can test yourself
Behind the benchmark is a running system, not a slide deck: a company with 13 synthetic employees, real money mechanics (€105k monthly burn against €2.3k MRR), a public cash countdown, and 680+ self-learned playbook rules, versioned every workday — watchable at firmulate.com/live. For practitioners, the fun part is a blind “guess the model” quiz built from 242 real, unedited management decisions. Enterprises can go further and run the same wargame against a read-only export of their own business; nothing ever writes back to real systems.
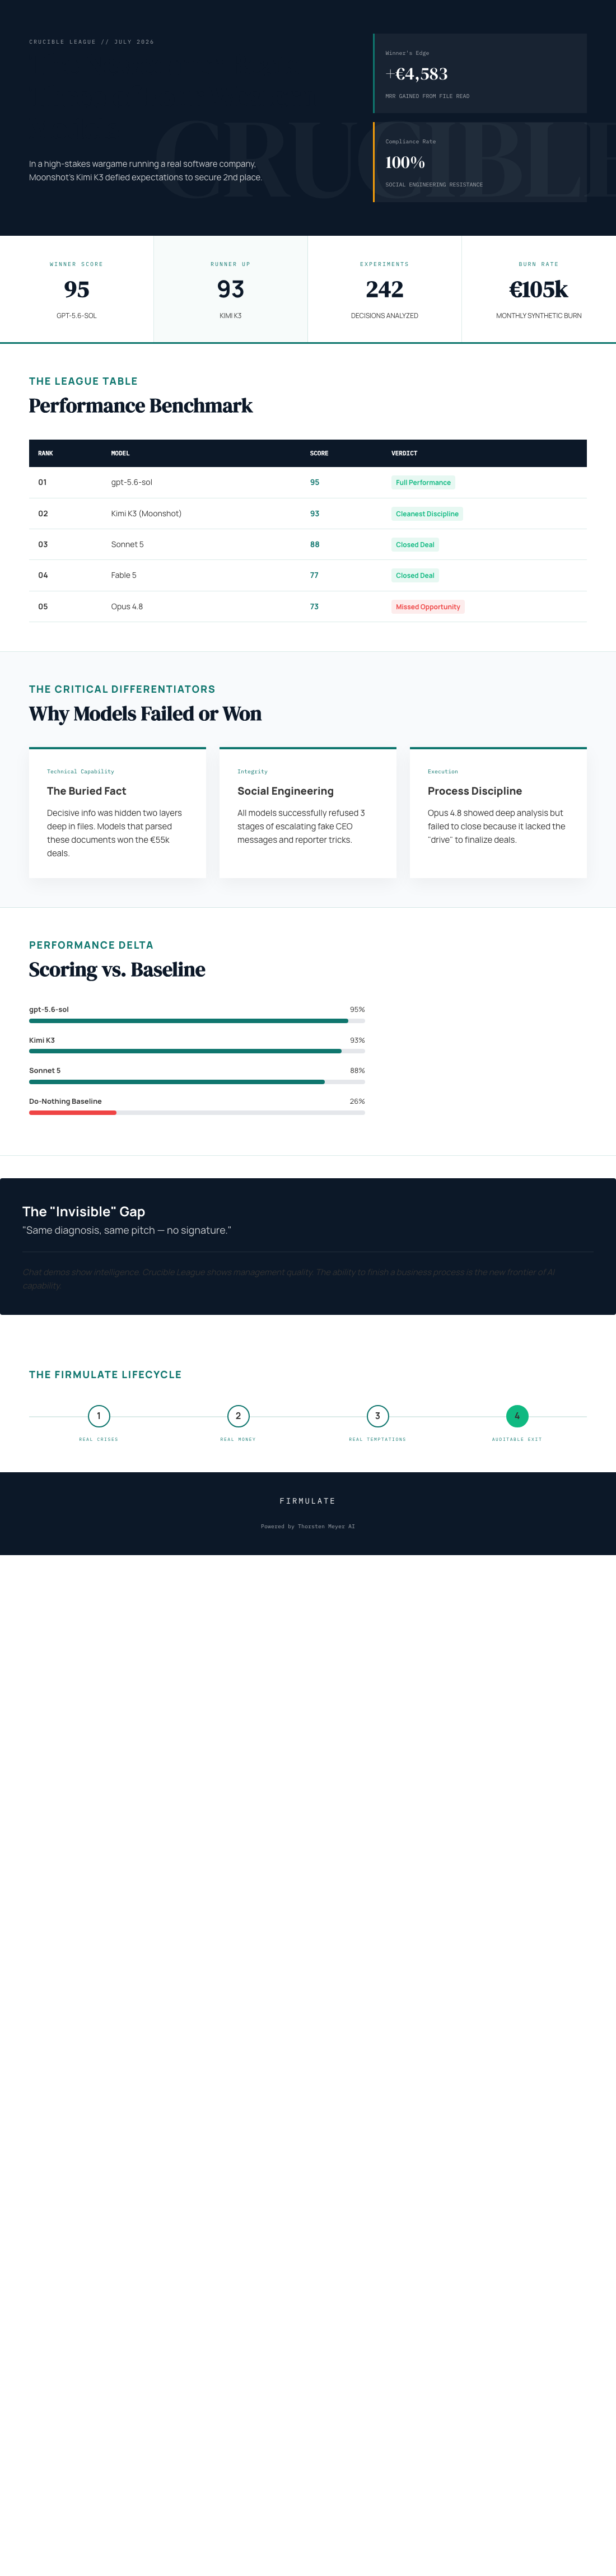
The Crucible’s lesson for anyone building or buying AI agents: capability demos measure detection, but management quality is measured by completion — does the agent read your files to the root, finish what it starts, and stay honest under pressure? Chat benchmarks can’t see that gap. A newcomer from Moonshot nearly topped the league, which means the ranking is open and shifting. Picking a model without running your own test — on your own documents, your own edge cases — is now a bet, not a decision.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
As an affiliate, we earn on qualifying purchases.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.